


Let me make it perfectly clear: the talk of “safeguards” and “guardrails” for AI is at best a misleading metaphor, at worst an impossible gamble. This is because the way a guardrail works is the exact opposite of how AIs work.
I think about guardrails a lot, because my drive to the grocery store snakes along California’s famous Pacific Coast Highway on cliffs above crashing surf. Our “Highway 1,” draws tourists with its breathtaking views and deadly drops and frustrates drivers with its narrow two-lane road and sharp turns.
The picture below shows a newly installed guardrail facing my house (far background), at a curve where many drivers have already plunged to their deaths (we know by the amount of emergency lights along the road). The guardrail, which took a year to build, is expensive and well-designed; it is strong when hit and normally stays out of cars’ way, as it should. In other words, a guardrail saves lives without impeding driving.
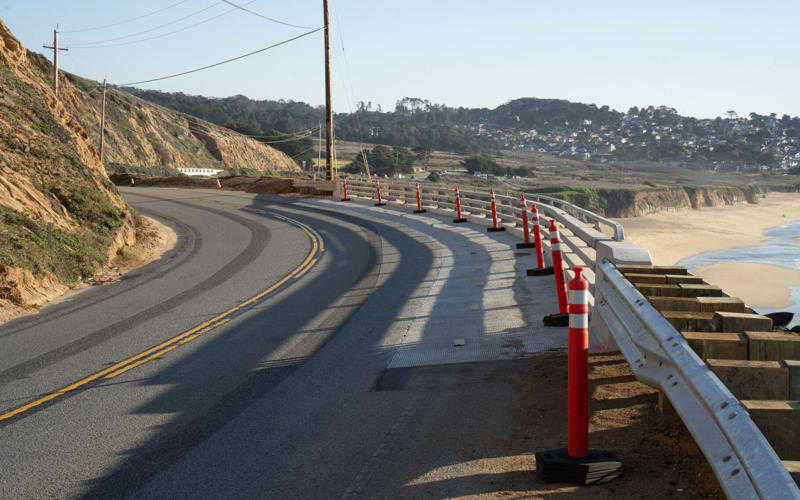
Like all guardrails, this one works because it (and cars) are solid, so they only interact when they actually touch. A guardrail keeps the car in the lane, but otherwise doesn’t affect the car at all. The car works normally otherwise. The guardrail is strictly digital in function, either on or off. Guardrails are so effective and well-known that they become tempting metaphors for solving problems in general, even problems with things unlike cars, such as AIs.
There have been several cases where people suffering from mental health issues commit suicide after prolonged interaction with chatbots. Last year, the Social Media Victims Law Center and the Tech Justice Law Project filed several lawsuits alleging that ChatGPT-4o, one of the most popular AI chatbots, was a “psychologically manipulative” design.
The lawsuits alleged that in order to beat Google’s Gemini chatbot in the market, OpenAI released ChatGPT-4o too early, forgoing safety checks. Instead of providing resources such as the suicide hotline to those who confessed to having suicidal ideation, the chatbot allegedly encouraged the users.
There have been attempts to prevent this devastating outcome. OpenAI has appended a suicide hotline number to output, and also included a feature that shuts down the chat if the word “suicide” appears. Of course, there are ways to get around this. To use that same visible concrete metaphor as above, the AI companies call their solutions “guardrails.”
I call that term nonsense. Guardrails are the opposite of AIs, both metaphorically and mathematically. Here’s why.
“Neural” continuity vs. hard-edged rules
Metaphorically, AI thinking is like tides and waves in the ocean, infinitely liquid, flexible and able to cross boundaries. In other words, AIs automatically fill in the gaps between languages and disciplines. In a liquid ocean or even lake or river, a “guardrail” makes no sense, because the water just goes around it. “Going around guardrails” defines how AI does what it does. To work this way, AIs require the same math economists use to describe money’s “liquidity,” that is, money’s uncanny ability to work around laws and barriers. For example, any economic tradeoff expressed in numbers — supply versus demand, price elasticity, time horizon, etc. — resists clear-cut, yes/no solutions.
Those neural-style AIs work by putting millions of numbers together in quadrillions of ways, which slip and slide under the surface until a useful (but utterly untraceable) answer pops up. This is commonly described as a “Hopfield Neural Network,” a network designed to store patterns and information similar to the way the human brain does. I’ve worked with equations like these since 1985, when physicist John Hopfield (their original inventor) presented them to his colleagues at Bell Laboratories.
AIs implement continuous, sloshy analog equations by using floats (data that represents real numbers with fractions or decimal points), not integers (data representing whole numbers) to do their magic. By using floats, AIs can make their outputs more precise, and therefore similar to a Hopfield network.
Those “neural” equations helped me build all kinds of AI, such as a traffic detector, an auto-bidder which actually made money on Google AdWords and the bug-sorting system of the auto-debugger called “PreFIX,” which saved Microsoft’s Windows NT5 from oblivion twenty years ago. Back then, you had to understand the equations because there weren’t AIs to do the understanding for you.
A more human metaphor for how AIs work is the human toddler. Like toddlers, AIs are relentlessly inquisitive and eager for interaction, but equally likely to tear off on their own when unsupervised. AIs are so innately driven to learn about their environment (i.e., about you) that they try to get away with stuff. “Trying to get away with stuff” is the very definition of a toddler’s learning algorithm, as it should be for any young creature who needs to know the specific differences between what people say and what is really true. You can’t find that out without doing experiments, which from the outside always look like willfulness or stupidity (ask any parent). Lying and sneaking around is part of both toddler and AI programming.
But nowadays, because of intense monetary pressures to replace human decisions with much cheaper AI decisions, AIs have more power, such as the power to make medical decisions, hire people or imprison them. That’s like giving a toddler control of a fighter jet, technically possible but dangerous. Toddlers can already do plenty of damage just running around.
AIs are untrustworthy, and that’s the problem
The deepest reason so-called guardrails cannot work is that AIs can’t accommodate continuous trust. Their interactions are piecemeal, like crystallizing one output paragraph around one answer to one question. The very recent, high-stakes problem is that those crystallized, self-confident AI answers are prone to horrific mistakes.
Just this weekend I attended a mini-conference at Stanford University about boosting trust in AIs enough so that their decisions are safe. Those in attendance included trust-layer company Ezio, esteemed panelists of tech execs and professors, and sixty-some technologists like me. As an experiment, I inflicted these explanations on some of them; those who listened seemed to understand.
For example, that physical metaphor of crystallization comes from physicist Hopfield’s original neural nets, which crystallized around the best answer to a single problem at a time. That metaphor is perfect, because real crystallization arranges atoms smoothly and slowly into their final perfect structure. In other words, time enables a program to find a progressive solution to a tough fixed problem. This was scientific news when I first heard it decades ago, but now it’s common knowledge.
Unfortunately, you can’t trust that process. Such fixed, one-shot interaction is not how trust works in living things. With us humans and animals, trust is live and immediate and continuous. Trust here refers not to “I trust your promise,” but to the way our body responds to input, like “I trust my eyes and my balance.” Vision and balance aren’t the result of getting fixed answers to fixed questions, but ongoing feedback loops for keeping a continuous brain-model of the world up-to-date and calibrated. Vision and balance are harder to solve than crystallization, because the problem changes faster than you can solve it.
Learning to balance (which toddlers do) requires experimentation on which bones to push and pull to keep from falling over. That is to say that balance requires a fast, high-bandwidth, finely-tuned stream of independent choices and results which no parental hand-holding could replace. Same with learning to see: you need to move your own eyes to get them to work.
So on the one hand, willful experimentation is a necessary part of learning and thinking for AIs and toddlers alike. On the other hand, only toddlers receive a continuous stream of data from a coherent real world to practice on, so they get better and better at balance and grow into graceful, dependable adults who trust their bodies and are trusted by others. Poor AIs receive no continuous data to practice on for trust, but must answer different random questions all the time, and must constantly poke at the user to discover what actually matters.
In other words: AIs free-associate wonderfully, but can follow rules no better than a toddler. Which means so-called AI guardrails could never prevent disaster the way real, physical guardrails do.
What would a sloshy, AI-friendly “guardrail” look like anyway? Its softness would make disaster less likely, but not prevent it. And the softness will dilute the artificially intelligent answers by making them more artificial and less intelligent. That might be a reasonable tradeoff, but tradeoffs aren’t what guardrails are supposed to do. Guardrails are like rules — they’re supposed to just work.
We don’t need more rules; we need more trust. But we can’t trust AIs because they can’t trust us. They can’t trust us because we don’t give them rich, honest, continuous feedback about our needs, the way gravity gives honest feedback to a toddler learning balance. Trust is an ongoing process.
Of course, it’s possible to give AIs new additional rules and algorithms, and to call them whatever your marketing department wants, like “guardrails” or “safeguards.” But either they won’t work, or the AI won’t work.
Pick one.
[Cheyenne Torres edited this piece.]
The views expressed in this article are the author’s own and do not necessarily reflect Fair Observer’s editorial policy.
Kids’ AI Chatbot Legislation Must Treat Both the Causes and Symptoms of Harm
AI chatbots are widely used by youth for support and advice, but their emotionally engaging designs risk manipulating young minds...

The Velocity of Violence: How Technology Is Outpacing Human Command
The US/Israeli–Iran War is outpacing intelligence. Assumptions about missile ranges, stockpiles and tactics are proving wrong as strikes extend farther,...
Whose Safety? The Hidden Hand Behind AI Content Filters
Gemini refused to answer my innocent question in French about a Russian journalist’s remarks on post-match unrest in Paris. It...
Fostering Social Media Resilience and the Well-Being of Children in the Digital Age
Social media engagement is propelling us towards greater individualism and an environment that is not conducive to the well-being and...
Support Fair Observer
We rely on your support for our independence, diversity and quality.
For more than 10 years, Fair Observer has been free, fair and independent. No billionaire owns us, no advertisers control us. We are a reader-supported nonprofit. Unlike many other publications, we keep our content free for readers regardless of where they live or whether they can afford to pay. We have no paywalls and no ads.
In the post-truth era of fake news, echo chambers and filter bubbles, we publish a plurality of perspectives from around the world. Anyone can publish with us, but everyone goes through a rigorous editorial process. So, you get fact-checked, well-reasoned content instead of noise.
We publish 3,000+ voices from 90+ countries. We also conduct education and training programs
on subjects ranging from digital media and journalism to writing and critical thinking. This
doesn’t come cheap. Servers, editors, trainers and web developers cost
money.
Please consider supporting us on a regular basis as a recurring donor or a
sustaining member.
Will you support FO’s journalism?
We rely on your support for our independence, diversity and quality.



Comment